Hire · AI Engineer
Hire an AI engineer who takes LLM features all the way to production
LLM integration, retrieval-augmented generation and tool-calling agents, engineered with schemas, evals, latency budgets and cost ceilings. My RAG system improved answer accuracy 23% over plain vector search, and my LLM classifier routes hotel requests at about 88% precision in production.
- 6 P@SHA ICT Awards
- 17 products shipped
- 6+ years in production
- 5★ Upwork rating
Why clients choose me as their ai engineer
- ExperienceSenior, and proven in production6+ years, 17 shipped products and 6 P@SHA ICT Awards. Co-Founder & CTO, leading 25+ engineers, and still writing the critical code myself.
- ValueSenior expertise at a fraction of US/UK ratesI work remotely from Islamabad, so you pay well below US and UK senior market rates for the same depth, with working-hour overlap for the UAE, UK, EU and US East Coast.
- Low riskFixed-price prototype firstA free call, then a working prototype on your real data in about two weeks at a fixed price. You see results before any larger commitment.
What I build
- 01LLM featuresGemini, GPT and Claude integrated into your product with strict output schemas, guardrails and fallbacks.
- 02RAG over your dataHybrid BM25 and vector retrieval, cross-encoder reranking and answers that cite their sources.
- 03AI agentsTool-calling agents that fetch data, file tickets and route work, with human hand-off when confidence is low.
- 04Evaluation and cost controlGolden test sets that block regressions, plus caching and model choices that keep running costs predictable.
- Gemini
- OpenAI
- Claude
- ChromaDB
- BM25
- Python
- FastAPI
- Redis
Proof: ai engineer work in production
- System pipeline
- Research PDFs
- Chunk + embed
- Hybrid retrieval
- Reranker
- Cited answer
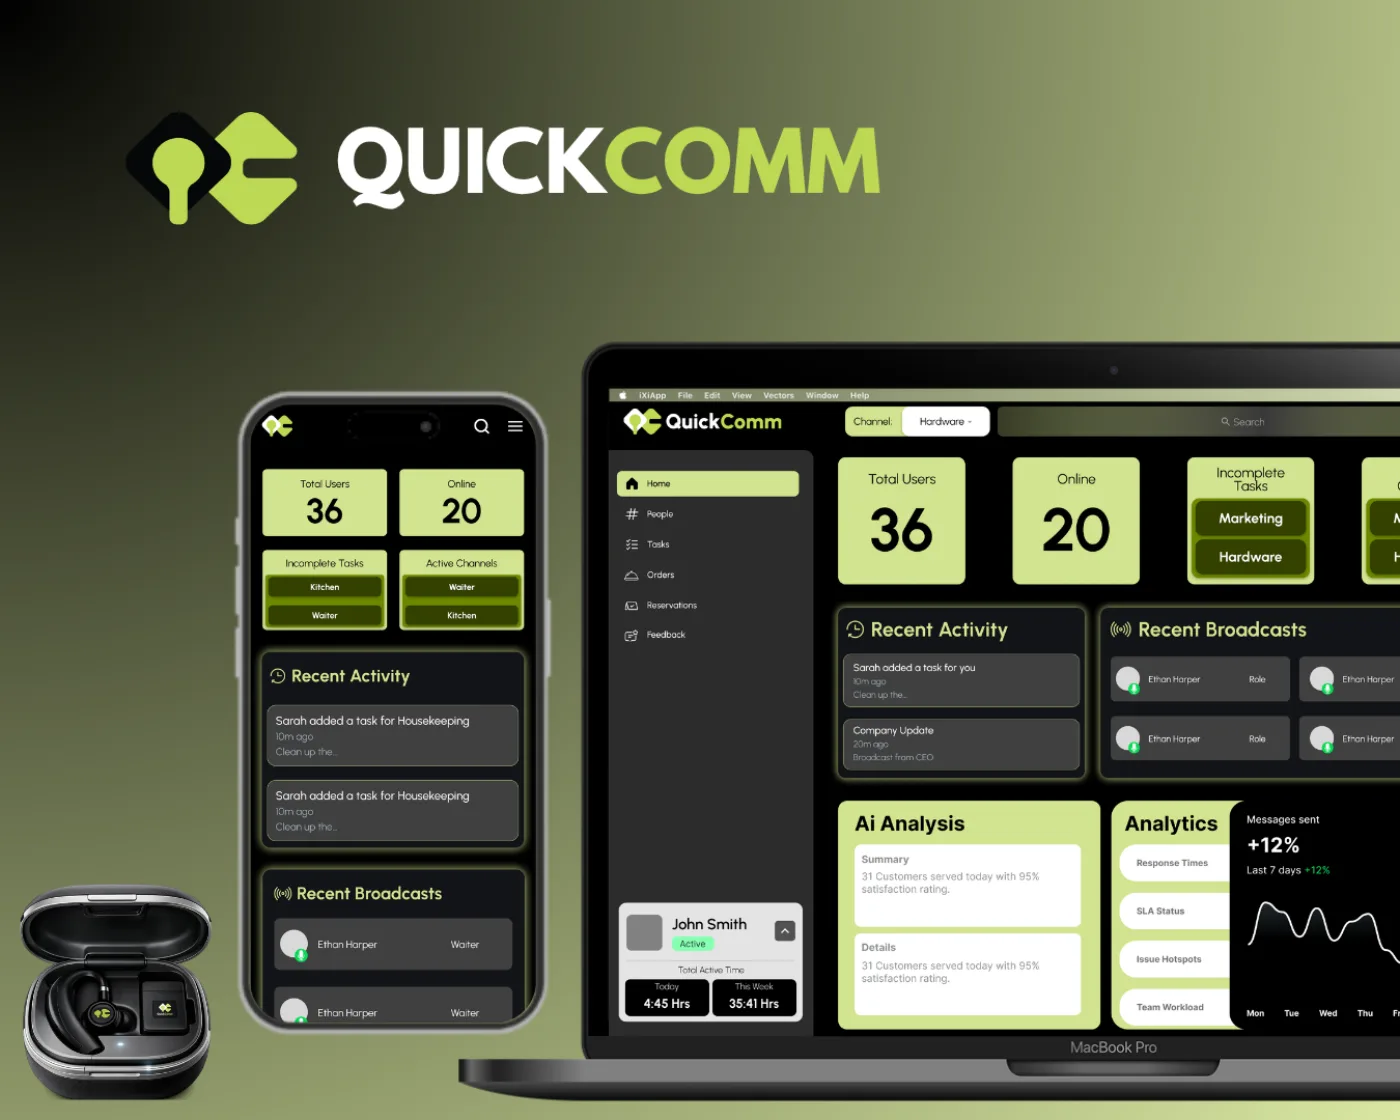 LLM · Real-Time · HospitalityQuickComm 94%+ transcription accuracy on noisy radio audio 5 P@SHA ICT Awards, 2026Read the case study
- System pipeline
- User speech
- Streaming STT
- Reasoning
- Voice synthesis
- Spoken reply
- System pipeline
- Live audio
- Streaming backend
- Transcription
- Translation
- Listeners
How I compare
| Senior US/UK freelancer or agency | Typical low-cost freelancer | Qalab | |
|---|---|---|---|
| Production experience | Senior | Varies, often junior | 6+ years, 17 shipped products, 6 P@SHA awards |
| Rates | Western senior rates | Low | Well below US/UK senior rates |
| Who builds it | Often delegated | Varies | I architect it and write the critical code |
| Risk | Hourly billing | Rework and hand-offs | Fixed-price prototype in about two weeks |
| Leadership | Usually extra | Rarely | Co-Founder & CTO, leads 25+ engineers |
The full engagement models, process and case studies are on my ai consulting service page.
Frequently asked questions
How long does it take to build an LLM or RAG feature?
A working prototype on your data takes about two weeks. Production hardening (evals, monitoring, cost controls, deployment) typically takes another four to eight weeks.
RAG or fine-tuning?
Most "ChatGPT for our data" requests are RAG: the knowledge changes and answers must be cited. Fine-tuning fits when you need a consistent style or a smaller model. I decide it in the audit.
How much does it cost to hire you as a ai engineer?
Every project is scoped on a free 30-minute call. Because I work remotely from Islamabad, you get senior, award-winning experience at rates well below US and UK senior market rates, and the prototype phase is quoted at a fixed price so your risk is capped.
Do you work with clients in the US, UK and UAE?
Yes. I have shipped for clients in UAE, UK, Australia and Pakistan, and work remotely with overlap for UAE, UK, EU and US East Coast hours.
Do you write the code yourself?
Yes. I architect the system and write the critical code myself. For larger builds I also lead engineers from my team at Quickgen Technologies, where I am Co-Founder & CTO.
Need a ai engineer? Let’s scope it.
Tell me what you are building. In 30 minutes you get an honest read on the approach, the risks and what it will take.